No. 01Opening thesis27 Oct 2026~10 min read
Intelligence Has a Meter Now
Since reasoning models arrived, how well an AI performs depends on how much thinking you pay for, and that quietly breaks the way we define, measure and sell intelligence. The opening essay of The Price of Thought.
Dhadi Sai Praneeth Reddy @dspraneeth07
· 10 min read
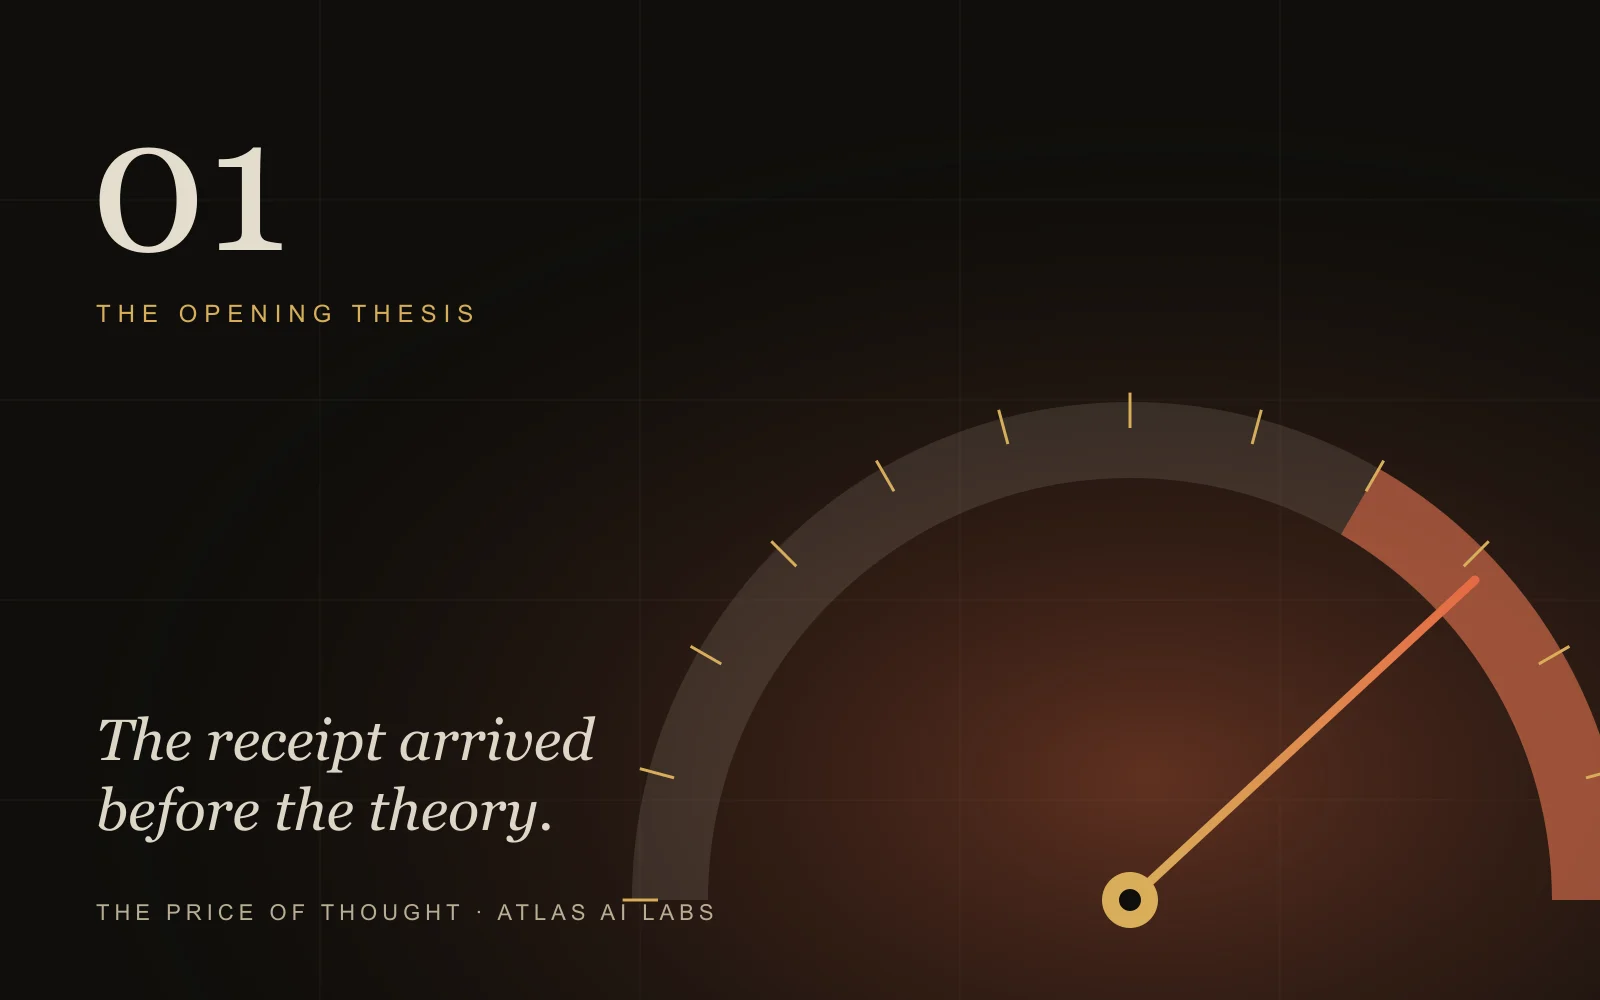
In December 2024 a benchmark result arrived with something AI results almost never carry: a price tag. The ARC Prize team, which maintains one of the field's most deliberately hard reasoning tests, reported that an early version of OpenAI's o3 scored 75.7% on its semi-private evaluation in one configuration. In a second configuration that used about 172 times more compute, it scored 87.5%.1 Same model. Same questions. Roughly twelve percentage points of additional "intelligence", bought by thinking for longer.
Most of the discussion focused on the score. The receipt was the more important part. For the first time, a headline result about machine reasoning was openly a function of how much the reasoning cost. This essay argues that this is not a footnote to modern AI. It is a quiet redefinition of what we have been measuring all along.
I · The receipt
For most of deep learning's history, intelligence was something you paid for once. You trained a model, which was enormously expensive, and then ran it for almost nothing. A forward pass cost roughly the same whether the question was trivial or profound. Deployed models had a fixed intelligence the way a printed encyclopedia has fixed contents.
That changed in September 2024, when OpenAI introduced o1 and published plots showing that accuracy kept rising as the model was allowed more "thinking" at inference time, not only as training compute grew.2 Within months the pattern was everywhere. DeepSeek's R1 showed in January 2025 that reinforcement learning could teach open-weight models to produce long reasoning traces, and that their performance grew with those traces.3 Through 2025 the major APIs turned thinking into a parameter: reasoning effort levels, thinking budgets, caps on reasoning tokens.4 Intelligence was now something you dialled.
A dial is a strange thing to attach to a mind. It implies that the same system can be more or less capable on demand, and that someone has to decide how much capability each moment deserves. That someone is now a developer setting a parameter, a product manager setting a default, or, increasingly, the model itself.
II · The assumption we never questioned
Almost everything in the AI conversation assumes that intelligence is a property of the artifact. We say "GPT-something is smarter than Claude-something" the way we say one engine is more powerful than another. Leaderboards rank models by single numbers. Procurement decks compare those numbers. Even debates about AGI usually ask whether a model has crossed some threshold.
That assumption made sense when inference was cheap and fixed. It does not survive the meter. If the same weights can score 75.7% or 87.5% depending on how long they think, "the model's score" is not a fact about the model. It is a fact about the model plus a spending decision. Leave out the spending decision and you have not described the system's intelligence. You have described one point on a curve and hidden the curve.
A benchmark score without a budget is like a car's top speed without mentioning the fuel. It is true, and it is beside the point.
III · Two scaling laws, two economies
The scaling-law era gave us a clean story. Kaplan et al. (2020) and Hoffmann et al. (2022, the "Chinchilla" paper) showed that pre-training loss falls predictably as you scale parameters, data and compute.5 That compute is capital expenditure: paid once, then amortised over every query the model ever answers.
Test-time scaling is a different kind of law. Snell et al. (2024) showed that spending inference compute well, by choosing among search, revision and verification strategies per problem, could on some tasks match a model many times larger.6 Brown et al. (2024) showed that when you simply sample many attempts, the fraction of problems for which at least one attempt is correct keeps rising with the number of samples over several orders of magnitude, as long as you have a way to recognise the right answer.7 This compute is operating expenditure: paid again on every query, in proportion to how hard you decide that query is.
That difference changes the economics of the whole field. When intelligence is capex, its marginal cost is near zero and the winner is whoever trains the biggest model. When a growing share of intelligence is opex, every answer has a marginal cost. The winner is whoever produces the most quality per unit of thinking, and whoever decides most wisely where that thinking goes.
IV · A model is not a point; it is a frontier
Once you accept the meter, the right picture of a model is a curve: expected quality on the vertical axis, thinking spent on the horizontal. Every serious system now has one. The curves have characteristic shapes. They rise steeply at first, flatten into diminishing returns, and on some tasks never reach the ceiling at any price.
Curves that cross are not a theoretical curiosity. Smaller, faster models answering with little deliberation routinely beat larger reasoning models on latency-bound, easy tasks, and lose badly when a hard problem is given room to think. A system's intelligence is its whole frontier. Ranking frontiers requires saying which part of the frontier you care about, and that is a question about your budget, not about the model.
This is why the ARC Prize had to report cost per task next to accuracy, and why cost-aware evaluation has been gaining ground.1 It is also why, privately, most AI teams now spend their time on a question that leaderboards ignore: given our latency limit and our cost per query, where on the curve should each request sit?
V · Intelligence as allocation: an old idea, suddenly operational
None of this would have surprised Herbert Simon. In 1955 he argued that real decision-makers are boundedly rational: they do not optimise perfectly, they satisfice within limits of time, information and computation.8 In 1991 Stuart Russell and Eric Wefald made the idea precise for AI. A rational agent with limited computation must treat its own thinking as an action, with costs and expected benefits, and choose computations by their value of computation: how much a further piece of thinking is expected to improve the final decision, minus what it costs.9
For thirty years that framework mostly lived in planning and game-playing research. It was elegant and seldom urgent, because mainstream systems had no real way to "think more" on demand. Reasoning models changed that. The theory of bounded optimality now has an obvious engineering home.
François Chollet's 2019 definition of intelligence as skill-acquisition efficiency, how much a system gets out of the priors and experience it is given, points the same way.10 Put the three ideas together and you get the working definition this series uses:
The second part is the one we rarely talk about, and the next figure shows why it matters.
VI · What changes when thought is metered
If intelligence is a frontier plus an allocation policy, several things change at once.
Evaluation changes. A single accuracy number becomes uninformative and sometimes misleading. Serious comparisons will report curves, cost per solved task, or quality at a fixed budget. Teams that adopt this early will make better model choices than teams still reading leaderboards.
Product design changes. Every AI product now has a budget policy, explicit or not. Does the user choose ("think harder")? Does the developer hard-code a level? Does the model decide? Each choice moves cost, latency, and the user's perception of intelligence. The 2025 move by several providers towards automatic routing between fast and deliberate modes is an early, crude version of letting the system decide.4
Pricing changes. Per-token pricing made sense when tokens were roughly proportional to value. With thinking tokens, a customer can pay ten times more for an answer that is no better, or a tenth as much for one that is exactly right. Pressure will build towards pricing on outcomes rather than effort.
Engineering changes. Latency budgets, cost ceilings and quality targets become one optimisation problem. "Prompt engineering" gives way to budget engineering: designing when a system escalates, when it stops, and when it hands off.
Strategy changes. If allocation is half of intelligence, a smaller lab with a superior allocation policy can sometimes beat a larger lab with a superior model, at the budgets customers actually pay for.
VII · The objections
"This is just inference cost. Prices fall every year; the meter will stop mattering." Per-token prices for a fixed level of capability have fallen fast. But William Stanley Jevons noted in 1865 that making a resource cheaper to use tends to increase total consumption of it.11 Cheaper thought gets spent on harder problems, longer agent runs and more parallel attempts. The frontier task, the one that matters most, has always been the expensive one. The meter moves; it does not disappear.
"Models will learn to budget implicitly; this is a temporary engineering detail." Possibly, and essay 08 takes this seriously. But "the model learns to allocate" does not make allocation irrelevant. It makes allocation a capability that can be done well or badly, measured, and improved. That is the thesis, not a refutation of it.
"Economics is a metaphor; minds are not markets." Fair warning. The claim here is narrower than it sounds. Wherever a resource is scarce and choices about it affect outcomes, the mathematics of allocation applies, whatever we call it. Thinking has become such a resource.
VIII · The question that runs through this series
If intelligence is now metered, everything downstream is rewritten: how we build systems, how we price them, how we power them and how we trust them. This series follows that rewriting over the next decade, one mechanism at a time. Its central question is simple to state and hard to answer:
The first part of the answer is uncomfortable. Today's most capable systems are extraordinary at thinking and surprisingly poor at knowing whether to. They write paragraphs of deliberation about trivial arithmetic and then answer an impossible question confidently after a few lines. They have a meter but no sense of value. That gap between the ability to think and the judgement about thinking is the subject of the next essay.
We used to ask whether machines could think. The sharper question now is whether they know what a thought is worth.
Behind this essay: the editorial brief
In December 2024, one of the most-watched results in AI came with a receipt: the same model, on the same benchmark, scored about twelve points higher when allowed roughly 170× more compute. We have spent seventy years asking how intelligent a machine is. We now have to ask how intelligent it is at what price.
Intelligence in AI systems has stopped being a fixed property of a trained artifact. It has become a curve, quality as a function of thinking spent. As a result, the decisive capability shifts from having intelligence to allocating it.
Through 2025–26, every major frontier provider exposed reasoning budgets as user-facing controls. Inference has become a recurring operating cost, not a one-off training cost. Products, pricing, benchmarks and infrastructure plans are all being rebuilt around this, mostly without a shared vocabulary for it.
Training-time vs test-time scaling; sampling, search and self-verification as forms of thought; accuracy–compute frontiers; amortised (capex) vs per-query (opex) intelligence; bounded rationality and metareasoning as the theory that predicted this.
“Which model is smarter?” no longer has an answer until you name a budget. Two models' curves can cross, so the leaderboard question is malformed. The real competitive variable is allocation skill.
Established: budget controls in APIs; test-time scaling results. Prediction: cost-normalised evaluation becomes standard; outcome-based pricing spreads; “budget policy” becomes an engineering discipline. Speculation: quality-per-joule becomes a consumer-facing metric.
Opens the series. Establishes that thought is now metered. Next: if thought is metered, can the machine itself judge when more thinking is worth it? (Essay 02)
We used to ask whether machines could think. The sharper question now is whether they know what a thought is worth.
Footnotes
-
ARC Prize, "OpenAI o3 Breakthrough High Score on ARC-AGI-Pub", December 2024. The semi-private evaluation: 75.7% in the high-efficiency configuration and 87.5% in the low-efficiency configuration, at roughly 172× the compute. ↩ ↩2
-
OpenAI, "Learning to Reason with LLMs", September 2024. ↩
-
DeepSeek-AI, "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning", arXiv:2501.12948, 2025. ↩
-
Provider documentation for reasoning-effort and thinking-budget parameters (OpenAI, Anthropic, Google), 2025; GPT-5 launch materials on automatic routing, August 2025. ↩ ↩2
-
Kaplan et al., "Scaling Laws for Neural Language Models", arXiv:2001.08361, 2020; Hoffmann et al., "Training Compute-Optimal Large Language Models", arXiv:2203.15556, 2022. ↩
-
Snell, Lee, Xu and Kumar, "Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters", arXiv:2408.03314, 2024. ↩
-
Brown et al., "Large Language Monkeys: Scaling Inference Compute with Repeated Sampling", arXiv:2407.21787, 2024. ↩
-
H. A. Simon, "A Behavioral Model of Rational Choice", Quarterly Journal of Economics, 1955. ↩
-
S. Russell and E. Wefald, Do the Right Thing: Studies in Limited Rationality, MIT Press, 1991. ↩
-
F. Chollet, "On the Measure of Intelligence", arXiv:1911.01547, 2019. ↩
-
W. S. Jevons, The Coal Question, 1865. ↩
- Established
Major frontier APIs expose user-controllable reasoning budgets (effort levels or thinking-token limits), and reported results improve with test-time compute on reasoning benchmarks.
- Prediction · Oct 2028
By October 2028, most headline frontier-model launches will report cost (or compute) per task next to accuracy on at least one major reasoning benchmark.
- Prediction · 2029
By 2029, the default experience in the leading AI assistants will choose its own thinking budget per request for most traffic, with user override as the exception.
- Prediction · 2030
By 2030, a meaningful share of enterprise AI contracts will price at least some workloads per completed outcome rather than per token.
- Speculation
“Quality per joule” or a similar efficiency figure becomes a consumer-facing marketing metric for AI, the way fuel economy is for cars.
Send the strongest objection
The best reader critique of this essay gets named, with permission, in the next one.
Send an objection- #The Price of Thought
- #Test-time compute
- #AI reasoning cost
- #Value of computation
- #Metareasoning
- #Bounded rationality
- #AI economics
- #AI evaluation
- #Atlas AI Labs