No. 04Paradigm shift3 Nov 2026~8 min read
From Models to Economies of Thought
Frontier AI is quietly turning from a single mind into an internal market of specialised computation, and the hard problems of that market are the old problems of economics.
Dhadi Sai Praneeth Reddy @dspraneeth07
· 8 min read
DeepSeek-V3, released at the end of 2024, has about 671 billion parameters, of which only about 37 billion are activated for any given token.1 For each token, a small learned router sends the computation to a handful of specialised "experts" and leaves the rest idle. Roughly 95% of the model sits out each decision.
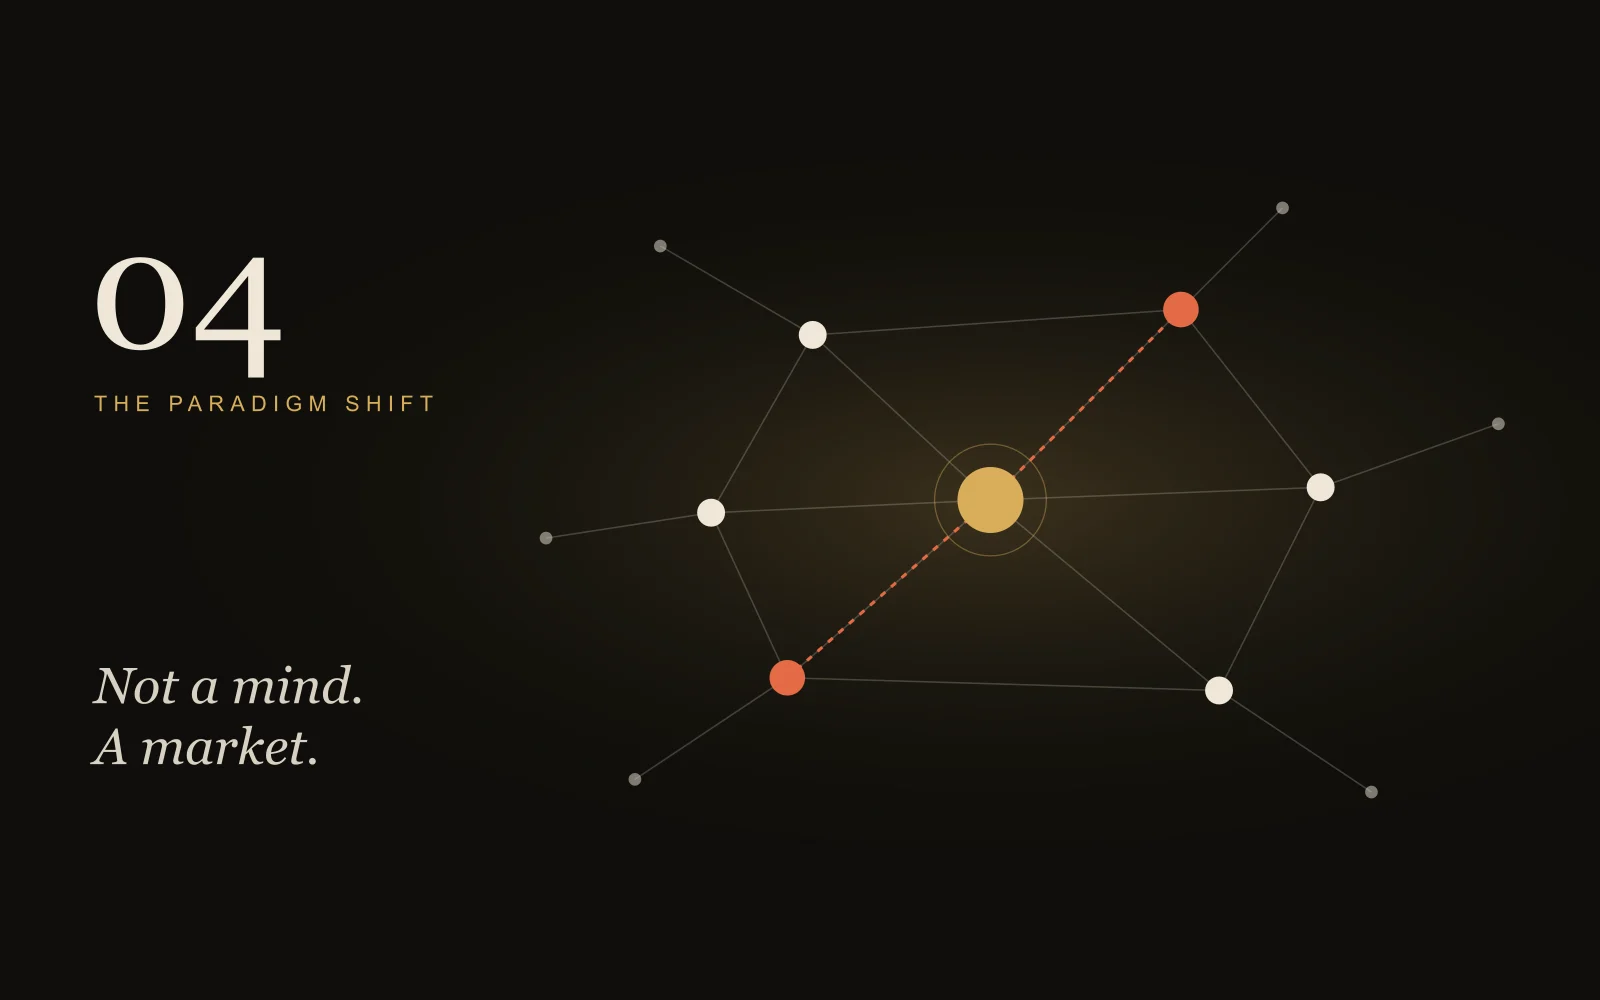
We still call this a model, singular, as if it were one mind. Structurally it is something else: a population of specialists and a mechanism that decides, millions of times per second, which of them each piece of work is worth paying for. That is not a brain. It is much closer to an economy.
I · The monolith myth
Public conversation about AI is organised around models as monoliths: this model versus that one, version numbers, a single entity that "knows" or "reasons". It made sense when a model was one dense network applied uniformly to every input. It is increasingly false at every level of the stack.
Look at what actually answers a hard request today. A router decides whether the request goes to a fast model or a deliberate one. The deliberate model is itself a mixture of experts, routing each token. It may call tools, spawn sub-agents, query a retrieval index and send drafts to a checker. The "intelligence" the user experiences is the output of a pipeline of allocation decisions, most of them made by small components that nobody outside the lab ever sees.
II · Conditional computation at every scale
The common principle is conditional computation: spend computation only where it is expected to matter. It now appears at four nested scales.
Within a token. Sparse mixture-of-experts layers, introduced at scale by Shazeer et al. in 2017 and simplified by the Switch Transformer in 2021, route each token to a few experts.2 Mixture-of-depths lets tokens skip whole layers.3
Within a query. Model cascades send a request first to a cheap model and escalate only when needed. FrugalGPT (2023) showed that a learned cascade over commercial APIs could match the best single model's quality at a fraction of the cost on its benchmarks.4
Within a task. Agentic systems decompose a goal into sub-tasks and assign them to sub-agents, tools or specialised models, each with its own cost and reliability.
Within an organisation. Companies are starting to route work between AI systems and people based on cost, risk and required verification. The organisation becomes the outermost layer of the allocator.
III · Hayek inside the network
In 1945 Friedrich Hayek published one of the most influential articles in economics, "The Use of Knowledge in Society".5 His argument was that the knowledge needed to allocate resources well is dispersed: it lives with the people closest to each local situation, and no central planner can gather it all. Prices solve the problem by compressing that dispersed knowledge into a single signal that anyone can act on.
An economy of thought faces exactly Hayek's problem. No central controller knows in advance how valuable each sub-computation will be. The relevant knowledge, such as how promising a reasoning branch looks or how confident a sub-agent is, sits in the components themselves. What a well-designed system needs is a price-like signal: a compact estimate of the value of further computation, which each component reports and the allocator can compare. Router scores, confidence estimates and value functions are early, crude versions of such prices. The value-of-computation estimate from Article 02 turns out to be more than a stopping rule. It is the currency of the whole system.
A router is a price system that has not yet realised it is one.
IV · Coase and the boundary of the model
In 1937 Ronald Coase asked a question that sounds naive: if markets are so efficient, why do firms exist at all?6 His answer was transaction costs. Using the market means searching, negotiating, contracting and checking, and when those costs are higher than organising the work internally, the work moves inside the firm. The boundary of the firm sits where internal coordination becomes more expensive than external contracting.
AI systems have the same boundary, and it is the most underrated design decision in agent engineering. Every time a system delegates to a tool, a sub-agent or another model, it pays a transaction cost. Context has to be serialised and passed. Instructions can be misread. Results have to be verified. Latency accumulates. Keeping the work "inside" a single long-context model avoids those costs but loses specialisation.
I call this the system's Coase boundary, the line between what it computes internally and what it delegates. The insight is that the line is set by coordination and verification costs, not by capability. Many 2026-era multi-agent architectures fail not because their agents are weak but because they delegate too eagerly. They pay heavy transaction costs, losing context in every handoff, to buy specialisation they did not need. Others fail the opposite way, by forcing one model to do work a cheap, checkable tool would do better.
V · What an economy of thought needs
If we take the analogy seriously, as a design discipline and not a metaphor, an economy of thought needs five institutions.
A currency. A common unit for the cost of thought: tokens, FLOPs, latency, joules or money, and an exchange rate between them for a given deployment.
Prices. Estimates of the value of further computation that are comparable across components.
Contracts. Specifications of what a delegated sub-task must deliver, written so that delivery can be checked. This is where Article 03's verifiers enter the economy.
Budgets that propagate. When a top-level task has a budget, sub-tasks should inherit portions of it, and unspent budget should flow back. Most agent frameworks still treat each call as if it were free.
Auditing. Traces of where thought was spent and what it bought, so the allocation policy itself can be evaluated and improved.
VI · How economies fail
Economies have characteristic pathologies, and economies of thought reproduce them faithfully. Runaway loops are the AI equivalent of a bubble: agents that call agents that call agents, each locally justified, collectively burning budget with no output. Congestion of shared resources appears when many components compete for a single context window and crowd out the information that matters, a tragedy of the commons. Goodhart failures occur when internal metrics such as router confidence or judge scores become targets and are gamed by the components they measure. Expert collapse in mixture-of-experts training is the most literal example: without balancing incentives, routers learn to send everything to a few experts, and the rest never develop. Engineers fix it with auxiliary "load-balancing" losses, which is to say with economic policy.
VII · Mechanism design is the new architecture
For a decade the central question in AI architecture was "what network?" The question emerging now is "what mechanism?" How are tasks routed, how is value estimated and reported, how are budgets divided and enforced, and how are participants kept honest? Economists have a name for designing rules so that self-interested or locally optimising components produce good global outcomes: mechanism design. I expect it to become one of the most important bodies of knowledge for AI systems engineers this decade. It is still almost entirely absent from their training.
An economy, however, cannot run on spending alone. It needs savings: a way to keep the results of past work so they don't have to be bought again. For thought, savings means memory, which is the subject of the next article.
The next great AI architecture may be designed
less like a brain and more like a well-run economy.
Behind this article: the editorial brief
In one of the most capable open models of 2025, roughly 95% of the parameters sit idle for any given token. Each token effectively "buys" a small team of specialists. We still call it a model. Structurally, it is already closer to an economy.
The architecture of AI is moving from monolithic models to systems that route computation among specialised parts: experts, cascades, tools, sub-agents, verifiers. Once that happens, the central design problem becomes mechanism design: how to price, route and audit thought.
Mixture-of-experts dominates frontier open models; routing between fast and deliberate models is in production; multi-agent systems are spreading. Each piece is discussed separately. Seen together, they are one architectural shift.
Conditional computation (MoE, mixture-of-depths); model cascades and routers; agent hierarchies; Hayek's knowledge problem; Coase's theory of the firm; failure modes such as runaway loops, shared-context congestion and Goodharted internal metrics.
Every AI system has a "Coase boundary": the line between what it computes internally and what it delegates. It is set by coordination costs (context transfer, verification, latency), not by capability. Most agent architectures put that line in the wrong place.
- The idle 95%
- The monolith myth
- Conditional computation at every scale
- Hayek inside the network
- Coase and the boundary of the model
- What an economy of thought needs
- How economies fail
- Mechanism design is the new architecture
Established: MoE, cascades, routing in production. Prediction: explicit budget propagation in agent frameworks; "router quality" becomes a headline differentiator. Speculation: internal auctions for compute among sub-agents.
03: generating and checking separate. 04: so intelligence becomes an economy of specialised parts. 05: every economy needs savings, and for thought that means memory.
The next great AI architecture may be designed less like a brain and more like a well-run economy.
Footnotes
-
DeepSeek-AI, "DeepSeek-V3 Technical Report", arXiv:2412.19437, 2024. ↩
-
N. Shazeer et al., "Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer", arXiv:1701.06538, 2017; W. Fedus, B. Zoph, N. Shazeer, "Switch Transformers", arXiv:2101.03961, 2021. ↩
-
D. Raposo et al., "Mixture-of-Depths", arXiv:2404.02258, 2024. ↩
-
L. Chen, M. Zaharia, J. Zou, "FrugalGPT", arXiv:2305.05176, 2023. ↩
-
F. A. Hayek, "The Use of Knowledge in Society", American Economic Review, 1945. ↩
-
R. H. Coase, "The Nature of the Firm", Economica, 1937. ↩
- Established
Sparse mixture-of-experts is standard in many frontier and open models; learned routing between models and between fast/deliberate modes is deployed in production assistants.
- Prediction · 2028
Major agent frameworks will support explicit budget propagation (a parent task's cost/latency budget is split among sub-tasks and enforced).
- Prediction · 2029
"Router quality", the ability to send each request to the cheapest component that meets its quality bar, will be a headline differentiator in enterprise AI platforms.
- Speculation
Some large agent systems will allocate compute among sub-agents through explicit internal auctions or bidding mechanisms.
Send the strongest objection
The best reader critique of this article gets named, with permission, in the next one.
Send an objection